The question
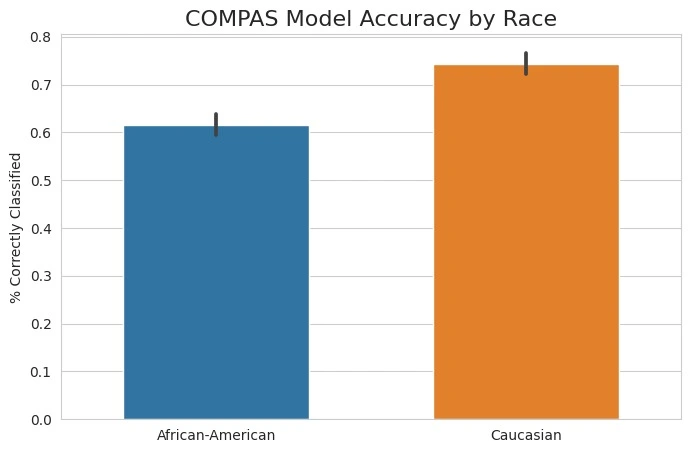
A model can perform well on average while producing different error patterns across groups. Removing a sensitive feature alone does not remove information carried by correlated features.
Fairness and privacy investigations
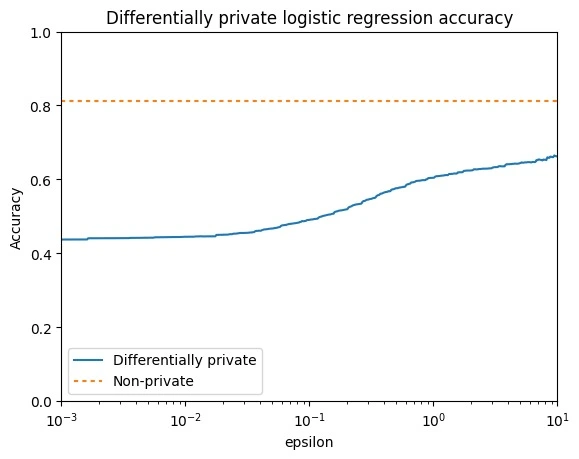
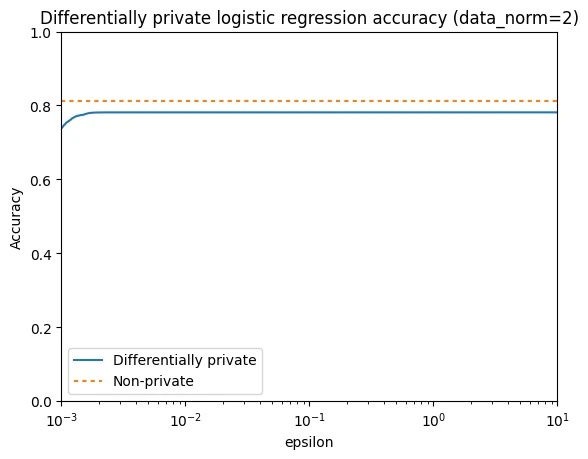
I examined classification disparities in COMPAS data, explored fairness interventions, built causal-analysis exercises, and tested differentially private regression models. These investigations connect evaluation choices with explicit assumptions about fairness and privacy.
Libraries and analysis workflow
I used pandas / NumPy and scikit-learn for data preparation, classification and evaluation, with Matplotlib for result plots. AIF360 and fairlearn supported group-fairness metrics and mitigation experiments, including Exponentiated Gradient Reduction and adversarial debiasing with TensorFlow. DoWhy supported causal modeling and refutation checks. In the privacy work, diffprivlib linear and logistic regression models were compared with scikit-learn baselines across privacy-budget settings. These were modeling investigations of tradeoffs, rather than a deployed decision system.